
Use Conversation Memory
Conversation memory lets an AI Agent reuse recent user and assistant messages across workflow runs. Enable it only when multiple executions belong to the same real conversation and the workflow can provide a stable conversation identifier.
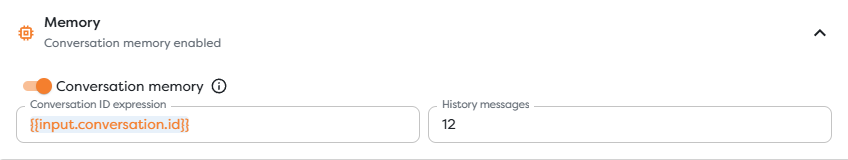
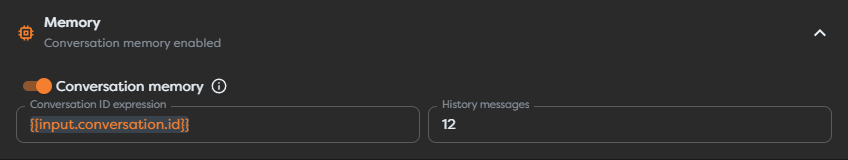
Understand how memory works
When Conversation memory is enabled, the block follows this sequence:
resolve conversation ID
-> load the last N user and assistant messages
-> send history with the current prompt
-> receive a successful response
-> append the rendered user prompt and assistant response
Memory is isolated by both the project and the resolved conversation ID. It is not one global history shared by every run or every project.
The AI Agent fails instead of silently becoming stateless when the conversation ID is empty or memory storage cannot be reached. Connect the Error port so these failures are visible and recoverable.
Choose a stable conversation ID
The conversation ID expression must resolve to the same non-empty value for every run that belongs to one thread, while producing a different value for unrelated threads.
| Conversation boundary | Example expression |
|---|---|
| Chat thread | {{input.chat.threadId}} |
| Support ticket | {{input.ticket.id}} |
| Attendee conversation | {{input.conversation.id}} |
| Account assistant | {{input.account.id}} |
The default expression is {{input.ai_context.conversation_id}}. Keep it only when an upstream block or trigger actually supplies that path.
Avoid using {{run.id}} when continuity is required. A run ID changes on every execution, so each run would create an isolated conversation. Also avoid a constant shared by all users because one person's history could influence another person's response.
If the same external identifier can exist in more than one channel, namespace it before it reaches the AI Agent. For example, pass values such as support:ticket-1842 and chat:thread-1842 instead of the unqualified value 1842.
Set the history limit
History messages accepts a value from 1 to 100; the default is 20. The limit counts individual user and assistant messages, not complete user-assistant pairs. A value of 12, for example, loads up to 12 recent messages before the current prompt is added.
Use the smallest history that preserves the context required by the task:
- shorter histories reduce request size, latency, and provider usage;
- longer histories preserve more context but can amplify stale instructions or earlier mistakes;
- the selected model still has to fit the history, prompt, attachments, tool definitions, and response inside its context limit.
Conversation memory retains rendered messages, not the original workflow object. Include stable facts in the current prompt or load them from a trusted source instead of assuming they will always remain in the recent history window.
Know what is stored
After a successful provider response, Builders appends the rendered user prompt and the assistant response to the conversation. A failed response is not appended as a successful exchange.
The memory toggle controls whether this block loads and appends conversation history. It is not presented as a history deletion control. Do not put credentials, secrets, or unrelated personal data in a prompt merely because it may be useful later.
Attachments are configured for the current request. When a later run still needs a file, attach that file again instead of assuming memory will resend its bytes.
Test isolation and continuity
Before publishing, run this test matrix:
| Test | Expected result |
|---|---|
| Two runs with the same conversation ID | The second response can use relevant information from the first successful exchange |
| Two runs with different conversation IDs | Neither response can use the other conversation's history |
| Missing or empty conversation ID | The AI Agent follows Error with a configuration or memory failure |
| History limit exceeded | Only the most recent configured number of messages is loaded |
| Memory disabled | The current prompt runs without loading or appending conversation history |
Use representative data and inspect the AI block rather than judging only the final workflow status. A handled AI failure can still result in an overall successful run.
Prefer stateless execution when possible
Leave memory disabled for one-off transformations, classification, extraction, summarization, and workflows where historical context must not change the answer. Pass the required state explicitly through input, Vault, a database, or a file when it should be deterministic and auditable.